Portrait of David Schraedel

David Schraedel

Data Engineering & Applied AI

I reduced a 30+ hour manual workflow to 5–8 hours, built a Python pipeline that made 6.7M+ words of YouTube transcripts queryable, and helped develop an AI tool designed to reduce the time and effort creators spend managing audience engagement.

I tend to notice what is not working, whether that involves a data pipeline, a product workflow, or my kitchen utensils. I would rather ask questions and work toward a useful answer than assume I already have one.

  • Python
  • AWS
  • SQL
  • Docker
  • Linux
  • Terraform
  • Systems Thinking
  • Falsifiable Product Strategy
  • Applied AI
  • Product Discovery and Validation
Let's chat

Distribution Center Forecast

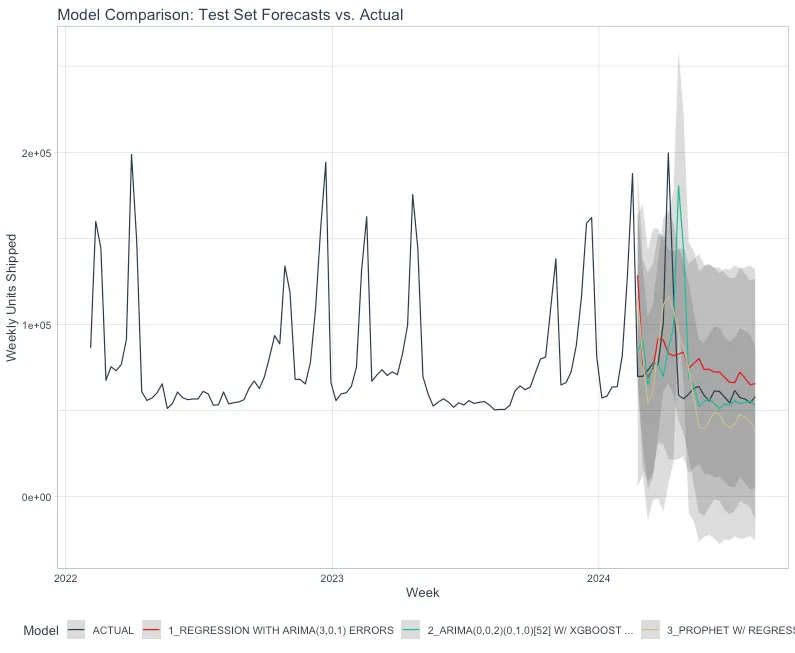
Weekly shipping volume at a distribution center follows annual seasonality and occasional holiday peaks that can triple normal volume.

I compared three modeltime approaches to see which handled that pattern best on a 24-week holdout, using external regressors for peak flags and environmental factors. Prophet captured seasonal structure most reliably (lowest RMSE), but peak weeks remained difficult — none of the models beat a naive baseline when spikes were rare in training. I refit the best model and deployed it as a Docker API.

  • R
  • tidyverse
  • tidymodels
  • modeltime
  • timetk
  • vetiver
  • Docker
  • AWS S3

Adventure Works Data Engineering Pipeline

With sales data in PostgreSQL, support chat in MongoDB, and clickstream events behind a REST API, disparate systems prevent stakeholders from tying campaigns to conversions or browsing patterns to purchases.

I built an end-to-end pipeline that lands all three sources in Snowflake via a watermark-based Python ETL processor and a Prefect-orchestrated API flow, transforms them through 18 tested dbt models with dbt Cloud CI, and exposes the compiled graph to Snowsight and MCP-compatible agents through a dbt MCP server.

  • Python
  • Snowflake
  • dbt
  • Prefect
  • Docker
  • PostgreSQL
  • MongoDB
  • SQL

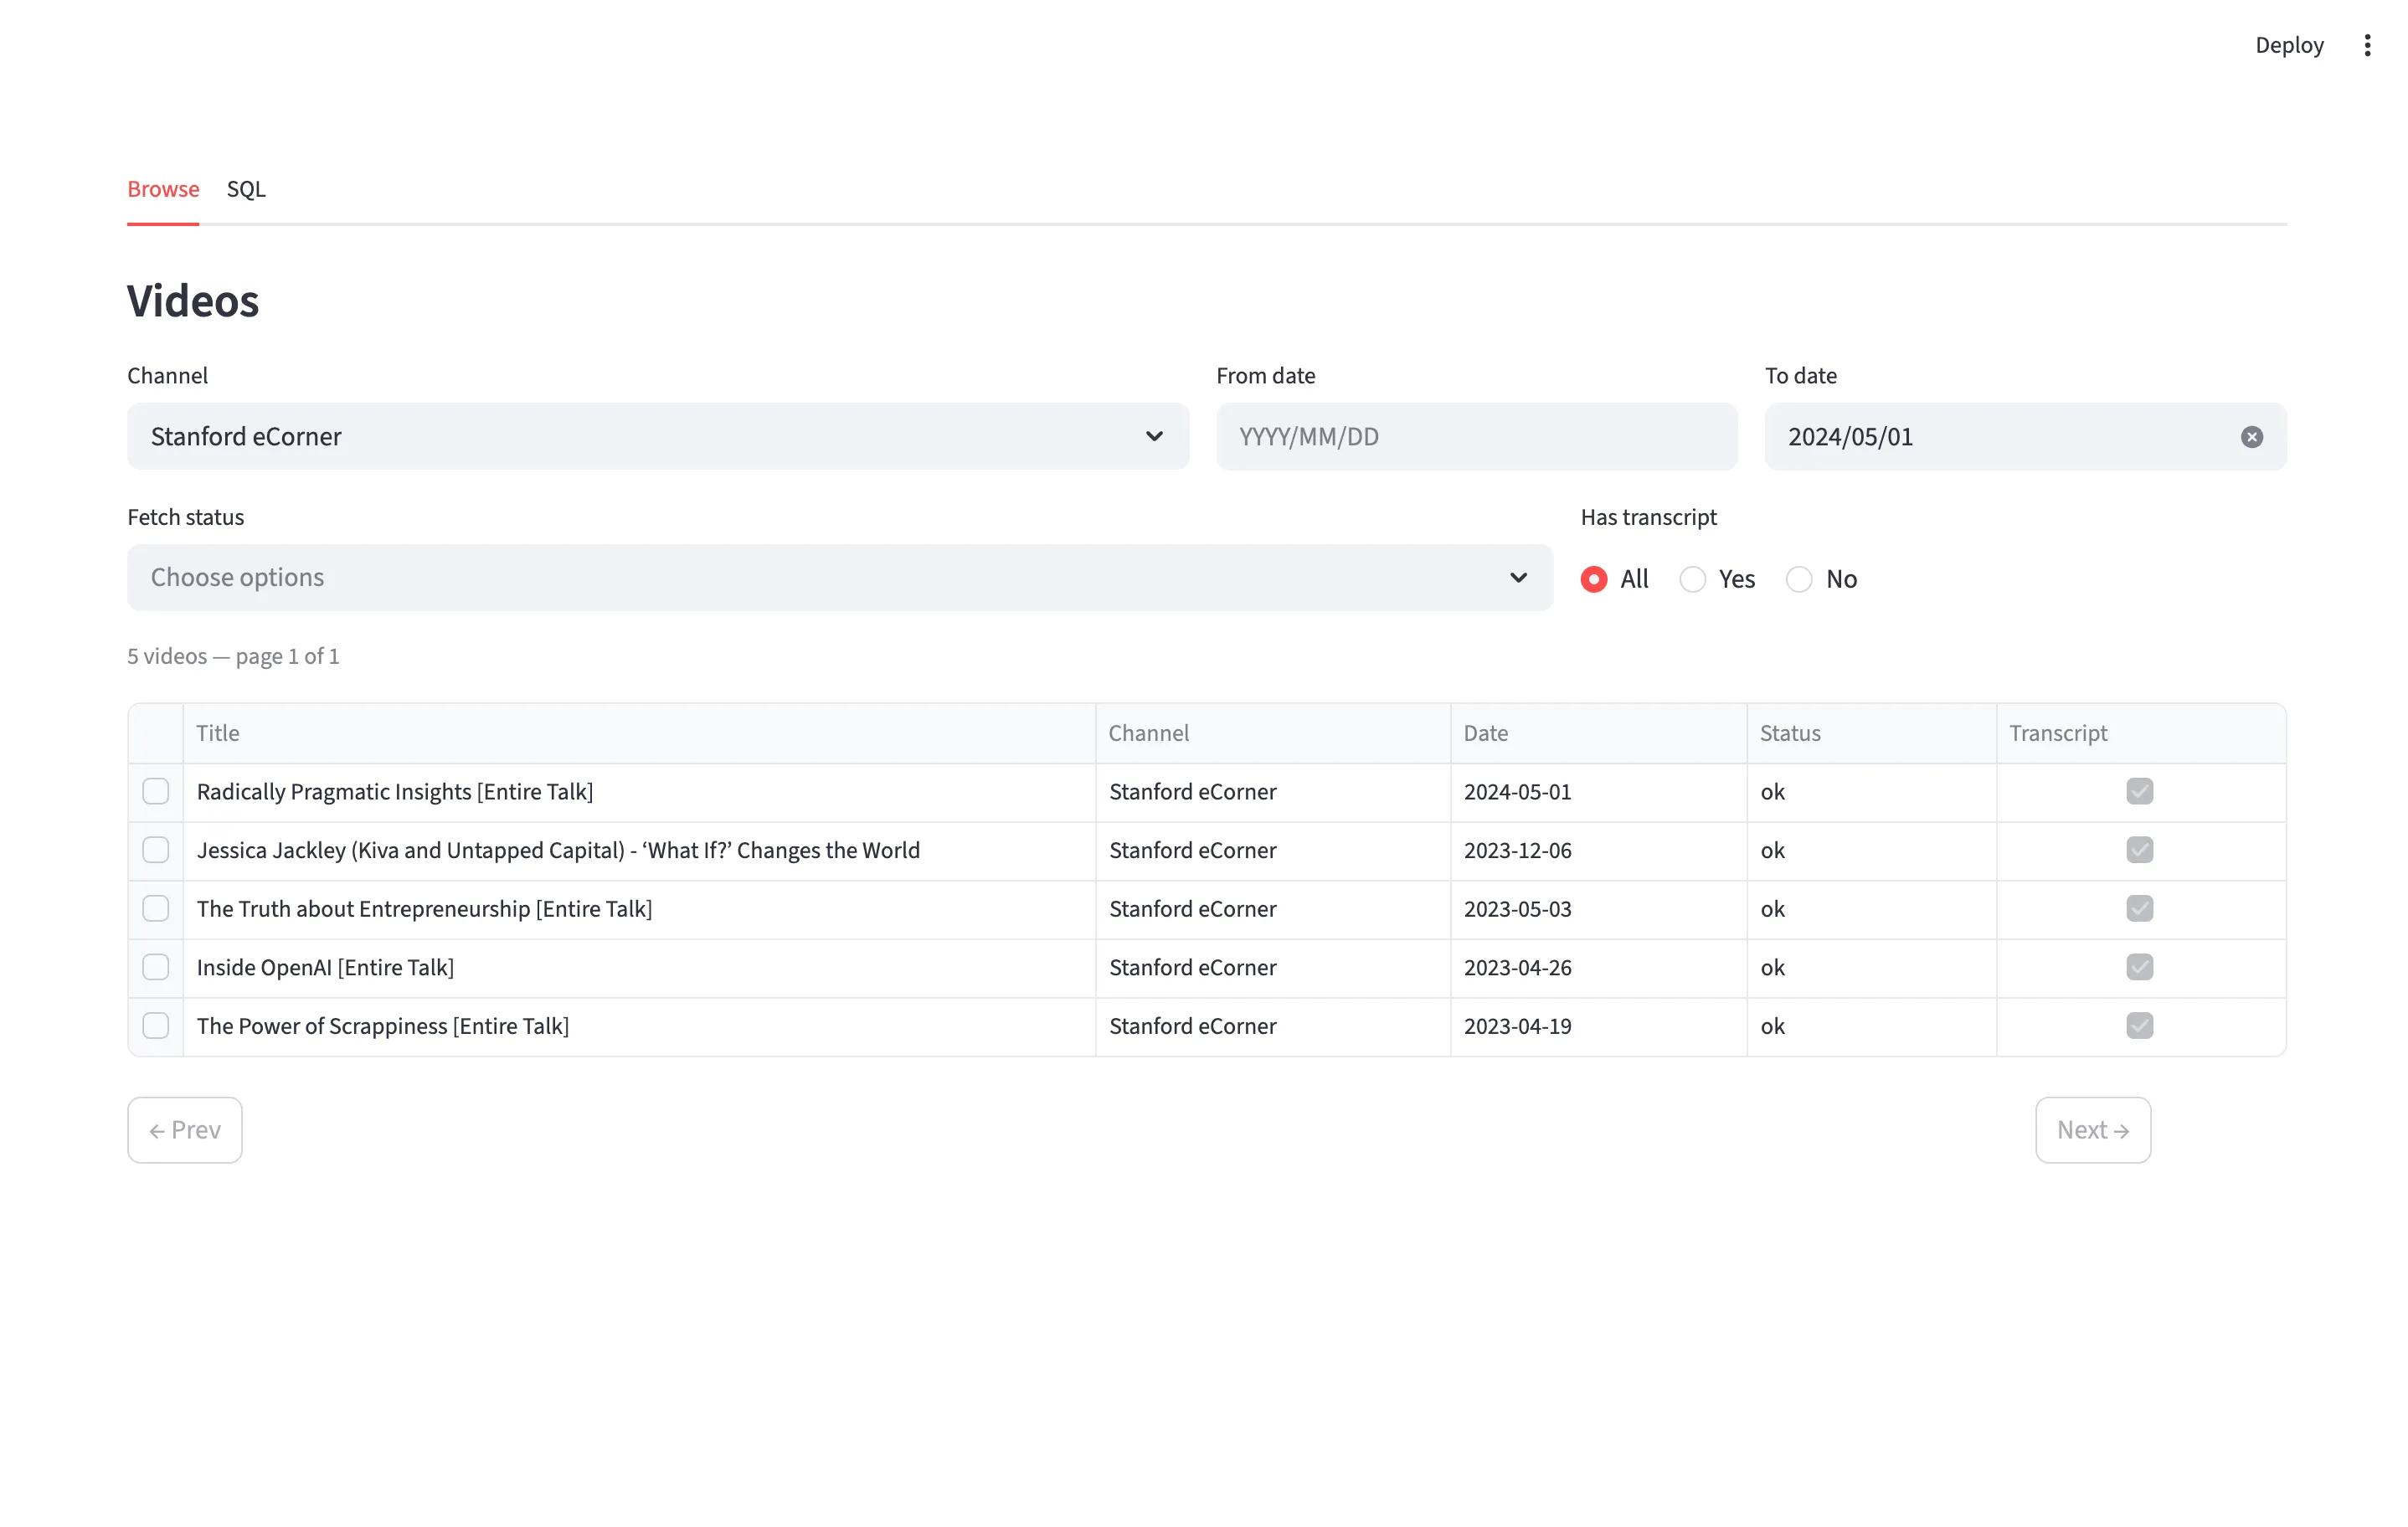
YouTube Transcript Pipeline

Hours of spoken content in YouTube playlists are locked in the UI and not queryable or exportable, and integrated tools like NotebookLM are limited in capability, control, and experience.

I built a Python pipeline, with an idempotent medallion architecture, that ingests YouTube playlists and turns ~6M+ words of transcripts into a clean, queryable dataset for analysis.

  • Python
  • DuckDB
  • SQL

Capstone Project - I AM Scale

Content creators with a large audience struggle to connect with the whole of their audience on an individual level, and current solutions to this are robotic and impersonal.

In a team of 5, collaborating with a local startup, I built and refined core features so creators can respond to an audience at scale without losing their voice and brand, using social media integrations and Amazon Bedrock AI services to roughly double response rate and let creators triage comments ~3x faster.

  • React
  • TypeScript
  • Node.js
  • Amazon Bedrock
  • AWS

All projects →

Let's connect

Working on something meaningful? I'd love to connect.

Reach out if you want a second pair of eyes and ears, need someone to test a product, or are hiring for a role where you think I could make a difference.

I'm always open to unconventional ideas. Or maybe you're doing the same-old exceptionally? Would love to help with that too.

Send me a message via email or LinkedIn.